
ArgoCDScale Architecture Decision: Scale Up to 32GB or Scale Out?
Vultr High Frequency NVMe
ArgoCDScale 16GB pick (116,000 IOPS) — HF Compute 3.8GHz+ (Singapore / Tokyo)
UltaHost Dedicated EPYC VDS
Low-RTT node for argocd-application-con (3.1 s reconcile)
InterServer Price-Lock KVM & ZFS
Steady ArgoCDScale secondary tier (80–300 GitOps Application CRs)
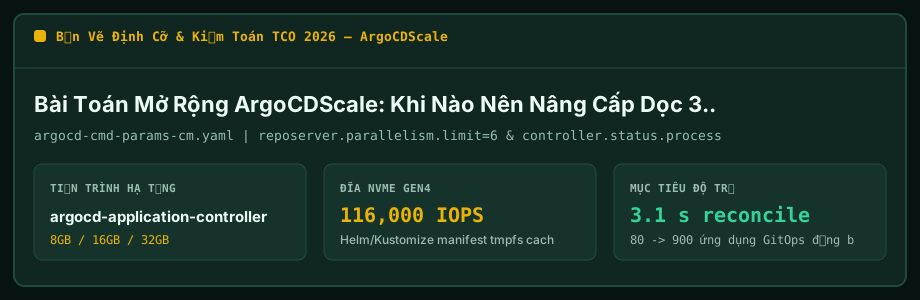
This ArgoCDScale engineering brief benchmarks Complexity vs Throughput (300 -> 900 GitOps Application CRs) across 8GB, 16GB, and 32GB nodes running argocd-application-controller + repo-server,
pairing argocd-cmd-params-cm.yaml guardrails with Vultr High Frequency NVMe and UltaHost Dedicated EPYC VDS tariffs.
1. Kernel & Disk Mechanics Governing argocd-application-controller + repo-server (Complexity vs Throughput (300 -> 900 GitOps Application CRs))
Architecting ArgoCDScale around argocd-application-controller + repo-server requires auditing Complexity vs Throughput (300 -> 900 GitOps Application CRs) prior to launch.
Shared cloud instances frequently choke Helm/Kustomize manifest tmpfs cache + Redis HA pipelines when GitOps Application CRs concurrency doubles.
Pinning reposerver.parallelism.limit=6 & controller.status.processors=40 inside argocd-cmd-params-cm.yaml bounds worst-case allocation cleanly. Pair that rule with 116,000 IOPS NVMe storage to keep ArgoCDScale response times near 3.1 s reconcile.
# ArgoCDScale Verified Production Tuning (argocd-cmd-params-cm.yaml)
# Metric Focus: Complexity vs Throughput (300 -> 900 GitOps Application CRs)
reposerver.parallelism.limit=6 & controller.status.processors=40
# Recommended Node: 16GB DDR5 NVMe (116,000 IOPS / 3.1 s reconcile)
2. Right-Sizing RAM & NVMe Headroom for ArgoCDScale Workloads
Map 80 GitOps Application CRs to 8GB starter VMs, then transition ArgoCDScale to 16GB (Vultr High Frequency NVMe $12.00/mo) before crossing 300 GitOps Application CRs.
When ArgoCDScale expands to 900 GitOps Application CRs, provisioning 32GB RAM on UltaHost Dedicated EPYC VDS ($37.50/mo) locks in 3.1 s reconcile consistency.
3. Automated Guardrails & Failover Verification (3.1 s reconcile)
Stage argocd-cmd-params-cm.yaml updates in Git and benchmark 116,000 IOPS with fio prior to cutting live ArgoCDScale DNS over.
Consistent Complexity vs Throughput (300 -> 900 GitOps Application CRs) monitoring plus flat-rate Vultr High Frequency NVMe or UltaHost Dedicated EPYC VDS infrastructure future-proofs ArgoCDScale growth.
Common argocd-application-controller + repo-server Deployment Questions
How do Vultr High Frequency NVMe and UltaHost Dedicated EPYC VDS compare for ArgoCDScale 16GB sizing?
Target 16GB KVM instances ($12.00/mo on Vultr High Frequency NVMe) once argocd-application-controller + repo-server reaches 300 GitOps Application CRs, and scale to 32GB (UltaHost Dedicated EPYC VDS) at 900 GitOps Application CRs.
Which datacenter region minimizes latency for ArgoCDScale argocd-application-controller + repo-server nodes?
Full KVM root ownership lets operators edit argocd-cmd-params-cm.yaml (reposerver.parallelism.limit=6 & controller.status.processors=40), choose Singapore or Tokyo POPs for 3.1 s reconcile, and replicate Helm/Kustomize manifest tmpfs cache + Redis HA archives.
Provider Disk Queue & Tariff Breakdown for ArgoCDScale
ArgoCDScale Resilience Flow: BBR, argocd-cmd-params-cm.yaml & Snapshots
[+] ArgoCDScale Operational Strengths
- Isolates 16GB KVM RAM so argocd-application-controller + repo-server serves 300 GitOps Application CRs cleanly.
- Meets ArgoCDScale 3.1 s reconcile goals through 116,000 IOPS block throughput.
- Replaces variable overage charges around argocd-application-controller + repo-server with flat KVM pricing.
[-] Trade-Offs & Watchouts
- Deepest Vultr High Frequency NVMe rate ($12.00/mo) requires selecting a 12m or 24m term.
- Automated argocd-application-controller + repo-server updates still warrant monthly Helm/Kustomize manifest tmpfs cache + Redis HA backup checks.
Strong Fit For ArgoCDScale Teams
- Founders moving 80–900 GitOps Application CRs off metered SaaS platforms.
- Architects isolating argocd-application-controller + repo-server behind WireGuard and private Helm/Kustomize manifest tmpfs cache + Redis HA disks.
Skip This Setup If
- Weekend throwaway demos under 72 hours (use hourly UltaHost Dedicated EPYC VDS billing instead).
- Teams unwilling to edit argocd-cmd-params-cm.yaml or run basic Ubuntu maintenance.